Robots.txt vs Noindex: What Actually Blocks Indexing?
Robots.txt blocks crawling, noindex blocks indexing — and mixing them up can leave a page in Google. Learn which control to use, with a worked example.
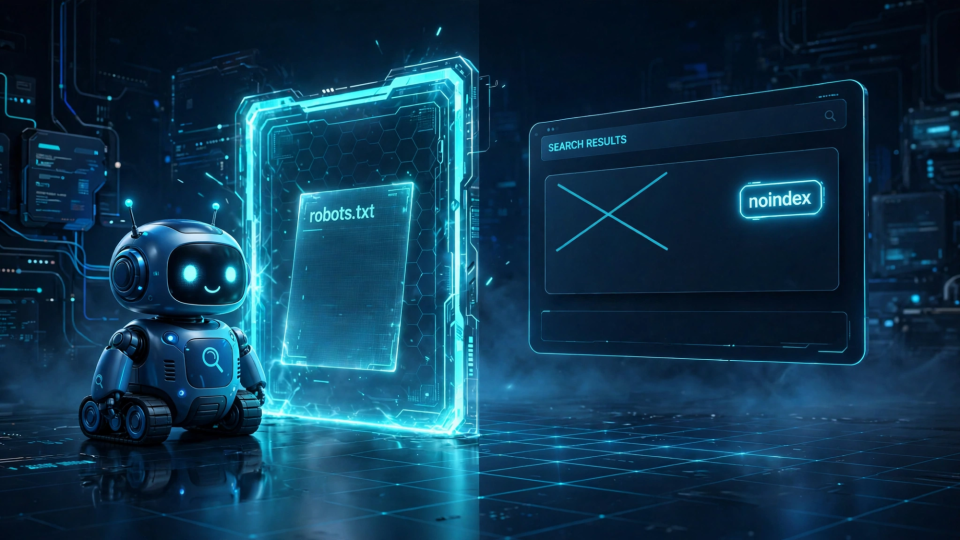
Search engines do two separate jobs with every page: first they crawl it, then they decide whether to index it. Robots.txt and noindex each control only one of those jobs, and they are not interchangeable — use the wrong one and a page you wanted gone can sit in search results. This guide explains what each control does, when to use which, and walks through a real worked example.
Crawling versus indexing: two different jobs
Crawling is fetching: Googlebot visits a URL, downloads the page, and reads its content. Indexing is what happens afterwards — Google decides whether the fetched page belongs in its index, the database of pages it can show in results. A page can be crawled without being indexed, and a URL can be indexed without ever being crawled.
That second case catches people out: if other pages link to a URL, Google may list it in results even without fetching it, usually as a bare URL with no title or description, because Google has no content to describe.
Robots.txt sits at the crawling stage: a plain-text file at your site root, fetched from an address like https://example.com/robots.txt, telling crawlers which paths they may fetch. Noindex sits at the indexing stage: a rule carried on the page itself, as a meta tag or an HTTP response header, telling search engines not to show that page in results. Because the rule lives on the page, the crawler must fetch the page to read it — and that decides almost every robots.txt versus noindex question you will face.
What robots.txt rules actually do
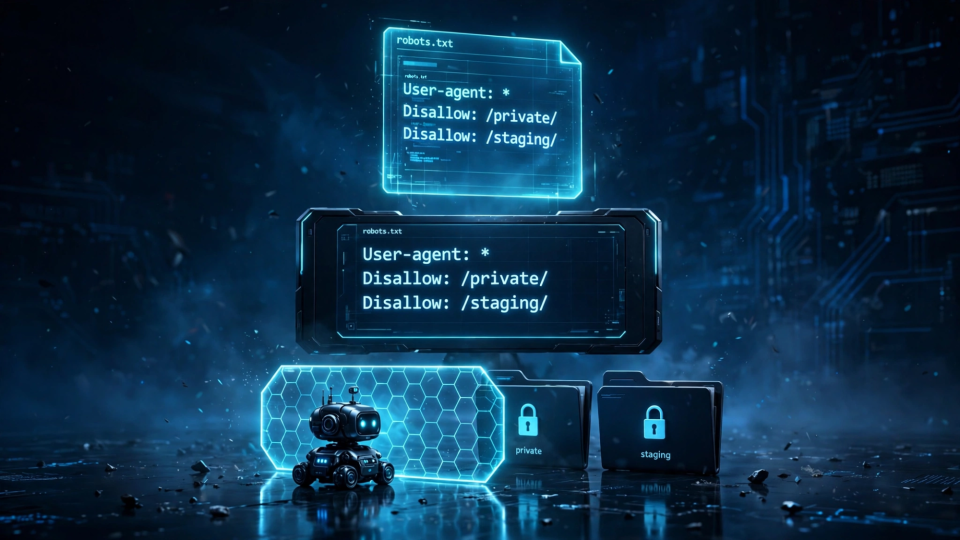
A robots.txt file is made of groups. Each group starts with one or more User-agent lines naming the crawler the rules apply to, followed by Allow and Disallow lines. A star as the user-agent means every crawler. A Disallow line lists a URL path prefix: any URL whose path starts with it is off-limits to that group. Paths are case-sensitive, and the match is a prefix match — Disallow: /private would also block a page called /private.html, so mind the trailing slash.
Here is a small, valid file:
User-agent: *
Disallow: /admin/
Disallow: /staging/
Sitemap: https://example.com/sitemap.xml
Google supports four directives here: User-agent, Allow, Disallow, and Sitemap. Two you will still see in old examples are ignored: Crawl-delay and a Noindex line inside robots.txt — Google does not support noindex in robots.txt at all, so writing one there changes nothing. Google also reads at most 500 KiB of the file and ignores the rest, so keep it short.
Robots.txt is a request, not a lock. Well-behaved crawlers obey it; malicious bots ignore it, and the file is public — listing a private folder advertises it. Never use it to hide sensitive content; that needs login protection. Its real job is crawl management: keeping search engines focused on the pages that matter instead of admin panels, staging copies, internal search results, and endless filter combinations. What it can never do is remove a page from results — that needs a rule the crawler can read, which means the page must stay crawlable.
What noindex actually does
Noindex tells a search engine not to show a page in results. For an HTML page, it goes in the <head> as a meta robots tag:
<meta name="robots" content="noindex">For resources with no HTML — PDFs, images, downloads — the same rule travels as an HTTP response header instead:
X-Robots-Tag: noindexBoth forms have the same effect: once Googlebot crawls the page and extracts the rule, Google drops it entirely from results, no matter who links to it. That is the key difference from a robots.txt block — noindex removes the page, while a disallow only stops the fetch and leaves the URL itself fair game for a bare listing.
Noindex has one hard requirement: the page must stay crawlable. Google states it plainly — for the rule to be effective, the page must not be blocked by a robots.txt file and must be otherwise accessible. If the crawler cannot fetch the page, it never sees the tag, and the tag does nothing.
Noindex takes effect on the next crawl, not on deploy: Google must re-fetch the page, read the tag, and process it before the listing disappears. A page crawled daily may drop within days; a rarely crawled page can linger for weeks. For urgent removals, use the removal tools in Google Search Console; a deleted page returning a 404 or 410 is eventually dropped too. Use noindex for pages that must exist for users but not in search — thank-you pages, login pages, internal search results. Do not use it for duplicates you want consolidated into one ranking URL; that is the job of a canonical tag, which is a hint rather than a directive.
The decision table: which control for which page
Start from the outcome you want, not the tool. "This page must not appear in search results" means noindex on the page, left crawlable. "Crawlers should not fetch this whole section" means a robots.txt disallow. "Several URLs show the same content and one should rank" means a canonical tag on the duplicates.
| Page type | Goal | Use | Watch out |
|---|---|---|---|
| Thank-you / order-confirmation page | Keep out of search results | Noindex meta tag | Do not disallow the page in robots.txt |
| Login / account pages | Keep out of search results | Noindex meta tag | They still need to be reachable by users |
| Internal search results | Stop crawlers wasting time | Robots.txt disallow | The block alone does not remove the URL |
| PDF or image file | Keep out of search results | X-Robots-Tag: noindex header | A meta tag cannot be added to a file with no HTML |
| Duplicate or parameter URLs | Consolidate ranking to one URL | Canonical tag | Noindex on a duplicate can remove the wrong version |
Worked example: a thank-you page and a search-results folder
Here is a real run through FBSubNet's free Robots.txt Rule Builder on a fictional site, example.com, with two problem areas: a thank-you page at /thank-you/ that must exist for users but never appear in search results, and an internal search folder at /internal-search/ that generates a new URL for every query — hundreds of near-empty pages wasting crawl attention.
The two areas need different controls. The thank-you page gets a noindex tag and stays crawlable, so Google can fetch it, read the tag, and drop it from results. The search folder gets a robots.txt disallow, because the goal there is to stop the fetching itself. Disallow the thank-you page too, and Google would never see its noindex tag — the URL could linger in results as a bare listing.
In the Robots.txt Rule Builder, the inputs were: Disallow paths /internal-search/ (one path per line), Allow paths left empty, and Sitemap URL https://example.com/sitemap.xml. Clicking Run tool produced this file, verbatim:
User-agent: *
Disallow: /internal-search/

Sitemap: https://example.com/sitemap.xml
The tool also showed: "robots.txt rules generated. Test on your actual site; robots.txt is not a security or noindex mechanism." The file is a starting point, not a guarantee — check each path against your real URLs before uploading. A folder mistyped as /internal-serach/ stays crawlable, and a folder blocked by mistake stays hidden until you fix the file. The tool runs entirely in your browser and uploads nothing.
Notice what is not in the file: the thank-you page. It is deliberately absent — blocking it would hide its noindex tag from Google. Instead, the page carries this line in its <head>:
<meta name="robots" content="noindex">That is the correct combination: the crawler fetches the page, reads the tag, and drops it from results on the next crawl. After publishing, check the live /robots.txt in a browser, then confirm the thank-you page still loads with the tag in its head and that no rule blocks it. If Search Console later reports the URL as "Indexed, though blocked by robots.txt", you have found the classic mistake — a disallow hiding the noindex tag — and the fix is to remove the disallow line and let Google crawl the page.
The four combinations, and the one to avoid
There are only four ways to mix crawling and noindex on a single URL, and only one of them causes real trouble.
| Crawlable? | Noindex? | What Google does | Use it for |
|---|---|---|---|
| Yes | No | Crawls and may index the page | Public pages you want found |
| Yes | Yes | Crawls the page, reads the tag, drops it from results | Thank-you and login pages |
| No (disallowed) | No | Does not fetch the page; may still list the bare URL if other sites link to it | Low-value sections |
| No (disallowed) | Yes | Never fetches the page, never sees the tag, and may keep the bare URL listed | Nothing — avoid this |
The fourth row is the trap: the disallow hides the tag, so the noindex never takes effect, and the URL can stay indexed as a bare link anyway. Fix it by removing the disallow line and letting Google fetch the page.
Mistakes that keep pages in search results
Most damage comes from a handful of repeatable errors. First, using a disallow to remove a page from results: it does not work — the URL can still appear, usually without a description, and the block hides the noindex tag that would actually remove it. To remove a page, add noindex and leave it crawlable, or delete it and return a 404 or 410.
Second, the reverse: adding noindex, then blocking the page in robots.txt during a cleanup — often by copying a staging file to production. The tag goes unread and the page stays listed. After any robots.txt change, check that no noindexed page falls under a disallow.
Third, putting a Noindex line inside robots.txt: Google ignores it, so the line gives false safety while nothing changes. The same applies to Crawl-delay — use the crawl-rate settings in Search Console instead. Fourth, treating either control as privacy or security: robots.txt is a public file listing what you blocked, and noindex only affects listings. Anyone with the URL can still open the page, so sensitive content needs login protection.
Fifth, never testing the file. A robots.txt file is code: after publishing, read the live file, test a blocked URL and an allowed URL, and confirm your homepage and key pages come back allowed. A broad pattern or a missing slash can block far more than intended, and the damage only shows up when pages start dropping out of results. For practical Disallow examples, read Robots.txt Disallow Examples and Common Mistakes.
Frequently asked questions
Does robots.txt remove pages from Google?
No. It only stops cooperative crawlers from fetching a URL; Google can still index a disallowed URL if other pages link to it, usually without a description. Use a noindex tag to remove a page, and keep the page crawlable so Google can see the tag.
Can I put noindex in robots.txt?
No. Google ignores the line entirely. Noindex belongs in the page head as a meta tag, or in the HTTP response as an X-Robots-Tag header.
What happens if a page is both disallowed and noindexed?
Google never fetches the page, never sees the noindex tag, and may keep the bare URL listed. Remove the disallow line so the crawler can reach the page and process the tag.
Putting it together
Robots.txt and noindex are not two ways of doing the same thing: robots.txt decides whether a crawler may fetch a URL; noindex decides whether a fetched page may appear in results. Use robots.txt to save crawl effort on sections that never need ranking, noindex on pages that must exist for users but never appear in search, and never both on the same URL. Before you publish any change, ask: if the page must leave the results, can Google still fetch it to read the rule? If yes, the rule will work. If no, fix the block first.